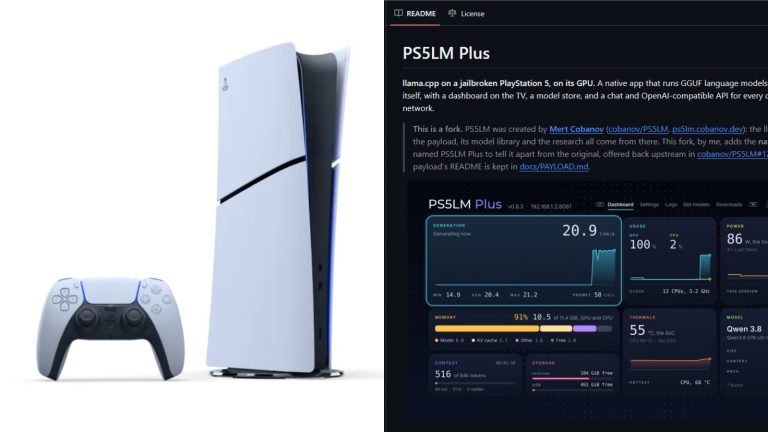
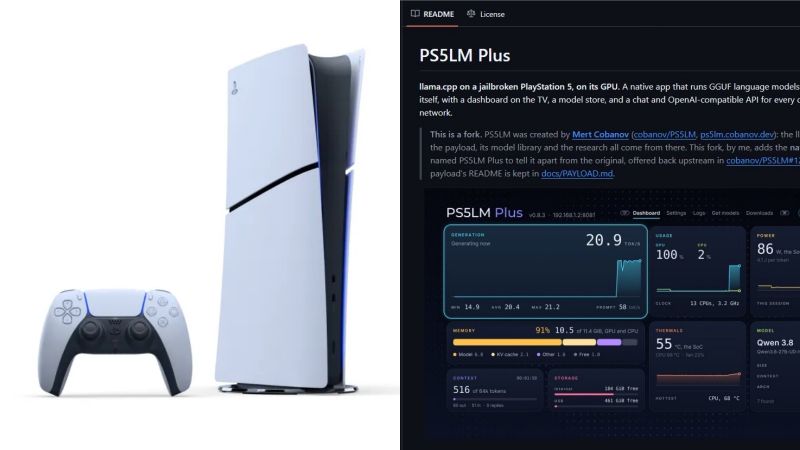
開發者 abhi245y 以資深 AI 工程師 Mert Cobanov 的 PS5LM(llama.cpp 移植專案)為基礎,打造原生 GPU 應用「PS5LM Plus」,讓越獄(Jailbreak,系統破解)後的 PS5 能在本機執行 Qwen3.8-27B 等大型語言模型。
除了透過 PS5 主機的 GPU 加速生成,PS5LM Plus 也內建網頁聊天介面,並可在區域網路中提供 API,讓 opencode、Codex、Claude Code 等工具連線使用。
根據外媒 Wccftech 報導,PS5 配備 16GB GDDR6 統一記憶體,由 CPU 與 GPU 共用,記憶體頻寬為每秒 448GB。PS5LM 初期版本由 CPU 負責模型運算,執行 27B 模型時,平均約一分鐘才能生成一個 token。
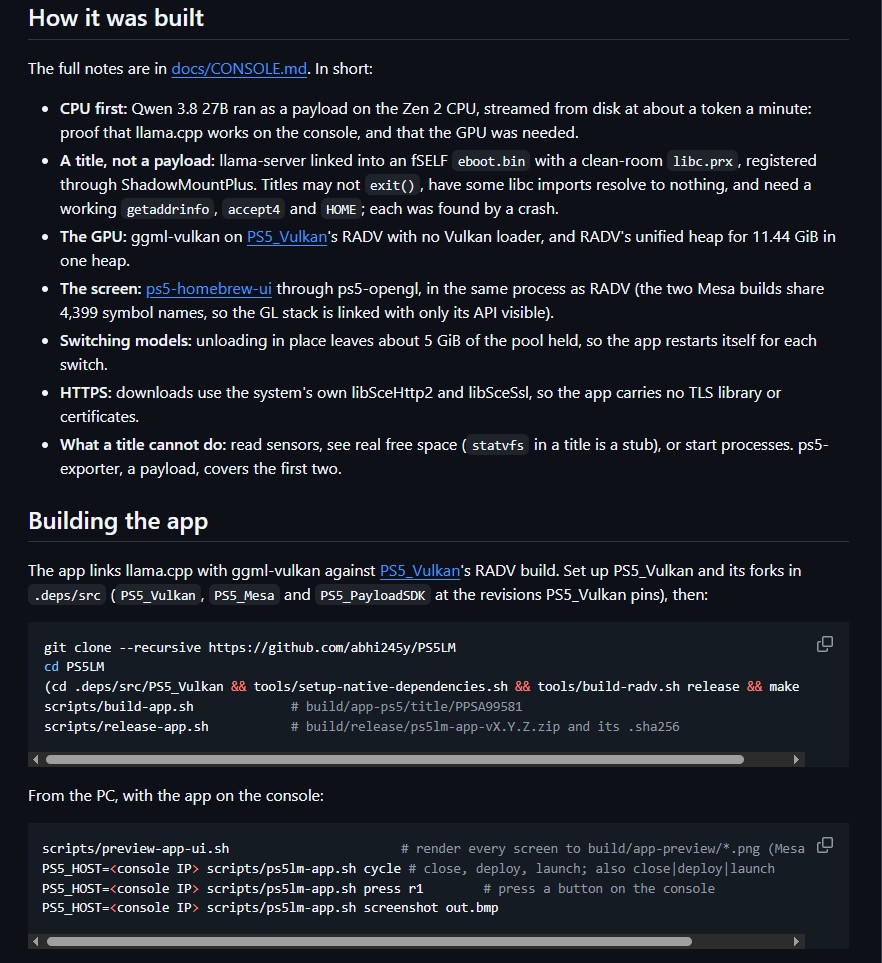
他透過移植 Mesa 開源 AMD 驅動程式 RADV,以 Vulkan 運算介面讓 llama.cpp 成為可在 PS5 上原生執行的應用程式,這項改動讓可用記憶體從僅有的 6GB 提升到 11.4GB,足以執行高度量化(quantization)的 Qwen3.8-27B。
Qwen3.8-27B 的「27B」代表模型約有 270 億個參數,可以把參數想成模型回答問題時要載入、運算的一大堆數值,數量越多模型通常越大,但不代表一定越聰明。
若以 16 位元精度執行,Qwen3.8-27B 需要 54GB 記憶體,只有搭載多張 GPU 或是單張 GPU 搭配大量系統記憶體的裝置才辦得到。
PS5 不具備這樣的配置,因此改在主機上執行 Qwen3.8-27B-UD-IQ2_XXS 版本,每個權重約以 2 位元儲存,模型大小縮減至 6.8GB,如下方右圖儀表板截圖所示。
 |
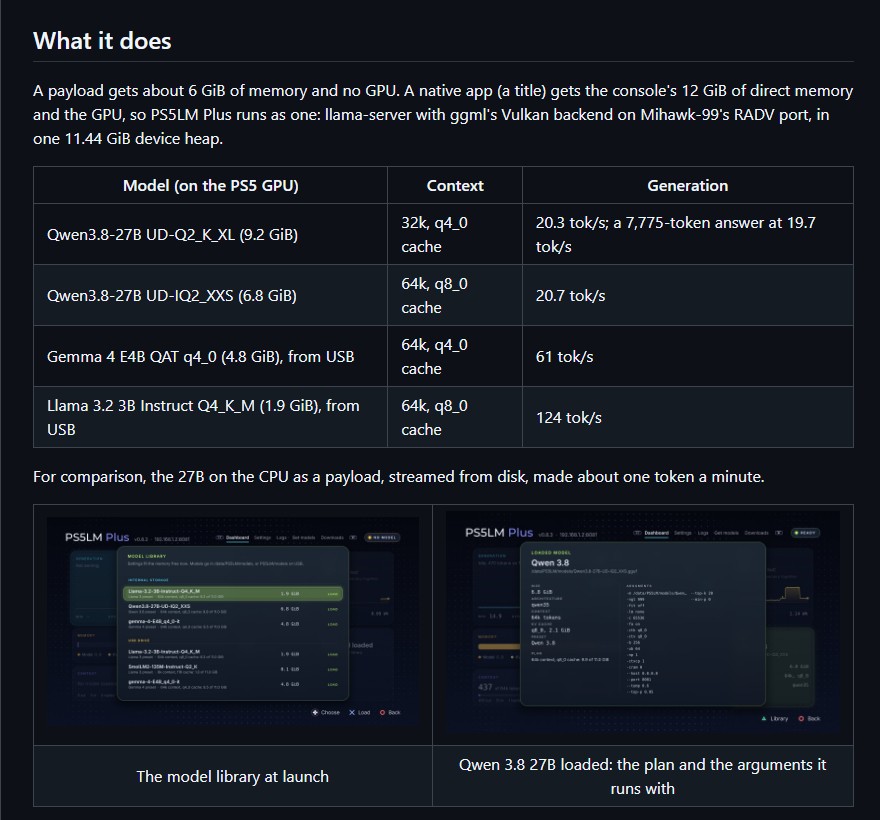 |
由於 PS5 具備不錯的記憶體頻寬,Qwen3.8-27B 的生成速度可達每秒 20.9 個 token,在當下 GPU 使用率為 100%,CPU 僅 2%,較小的模型在 PS5 的運作速度更快,Gemma 4 E4B 約每秒 61 個 token,Llama 3.2 3B 則達到每秒 124 個 token,整機總功耗為 86W,PS5 溫度維持在幾乎全開 54°C。
abhi245y 還在 GitHub 頁面提到,PS5LM Plus 在區域網路的 8081 連接埠提供網頁聊天介面,使用者可以從同一網路中的裝置開啟頁面與模型對話,它也相容 OpenAI 與 Anthropic API,讓 opencode、Codex、Claude Code 等工具連到 PS5 上執行的模型。
對一台原本只用來玩遊戲的主機來說,能當作 AI 本地伺服器實在不簡單,但還是有不少限制,像 16GB 記憶體只能執行閹割版的 27B 大型語言模型(LLM),或規模小得多的 AI 模型,實際使用可能無法體驗到理想的品質,此外,要在 PS5 上執行原生版 llama.cpp 必須先越獄,可能導致 PSN 帳號再跑連線遊戲時被停權。
A jailbroken PS5 is now being used to run a powerful AI model directly on the console.
A project called PS5LM has managed to run Qwen 3.8 27B, an AI model with around 27 billion parameters, using the PS5’s GPU.
The PS5 has only 16GB of memory, so the AI model needs heavy compression to fit, even with that limitation, it can generate around 21 tokens per second.
Smaller AI models are much faster. Tests reached around 61 tokens per second with Gemma 4 E4B and up to 124 tokens per second with Llama 3.2 3B.
During the test, the PS5’s GPU was working at 100%, while the CPU was barely being used. The console used around 86W of power and reached about 54°C.
— Pirat_Nation 🔴 (@Pirat_Nation) October 14, 2026
来源:查看原文